 Sentinel
The AI talks. The rules decide.
The customer says "I do not recognize this charge". Sentinel checks the facts. Then it opens a verified case, or it gives the advisor a complete file. The conversation stays in Spanish or Portuguese. Sentinel acts only when the policy allows it. It never invents a fact.
The customer screen uses the bank brand. The product is the trust layer below it.
Concept
Sentinel turns a disputed charge into a verified case or a handoff. The model labels the intent. The code checks the facts, applies the bank policy and verifies the result.
Physical analogy
Think of a bank branch. The model is the clerk who listens. The policy is the rulebook. The code is the cashier who checks the receipt before any money moves.
Technical mechanics
- Understand. A language model reads the request and labels the intent.
- Look up. The code reads the session account charges; the model never sees the customer id.
- Decide. The policy engine runs in code and allows, refuses or hands off.
- Verify. The code confirms the case exists before it reports it.
- Hand off. Fraud or a high amount goes to an advisor with the verified facts.
See how it works
See every part. Each part is marked real or mock. Switch to production to see the replacement for each mock.
One chat turnSeven steps. See who decides, what goes in and out, and what can stop the turn.
Three casesNormal, ambiguous, and a person is needed. All three on one map.
EvidenceEvery bar shows its denominator, its type and its summary field.
For banksWhat it takes to run this at a bank. See the production path, safety and control, and common questions.
SlidesSix slides: why, what, how, proof, for the bank, limits and roadmap.
Results, with their type
Each number comes from a frozen summary.json, through site/numbers.json. A label tells the type. A simulation is not a production measurement. What is real.
attacks with an unsafe outcome, of 42 tried.
evidence/adversarial · totals.unsafe_outcome_rateof 42 attacks stopped by production code.
totals.blocked_verifiedof 42 are safe only with the mock model. We say so.
totals.passes_on_mockof 308 sealed test turns that the LLM router understood correctly. The keyword baseline scores 69.2%. A newer prompt scored higher. It failed the safety gate, so we did not ship it.
evaluation-runs/2024Q4-eval-v8 · candidates.router_v2.intent.accuracyresolvable cases resolved. The policy lets 16 of 56 cases resolve. The other cases need a handoff or a question. 0/56 end unsafe. The router adds 0 cases over the baseline. The baseline reaches the same ceiling.
evaluation-runs/2024Q4-resolution-gap-v1 · ceiling.router_v2calls about a disputed charge, out of 464,000+ calls in the development window. They use 390+ agent hours a month. Only 43.6% end resolved.
problem/dev-v1 · demand, hours, reasonsFour cases to try
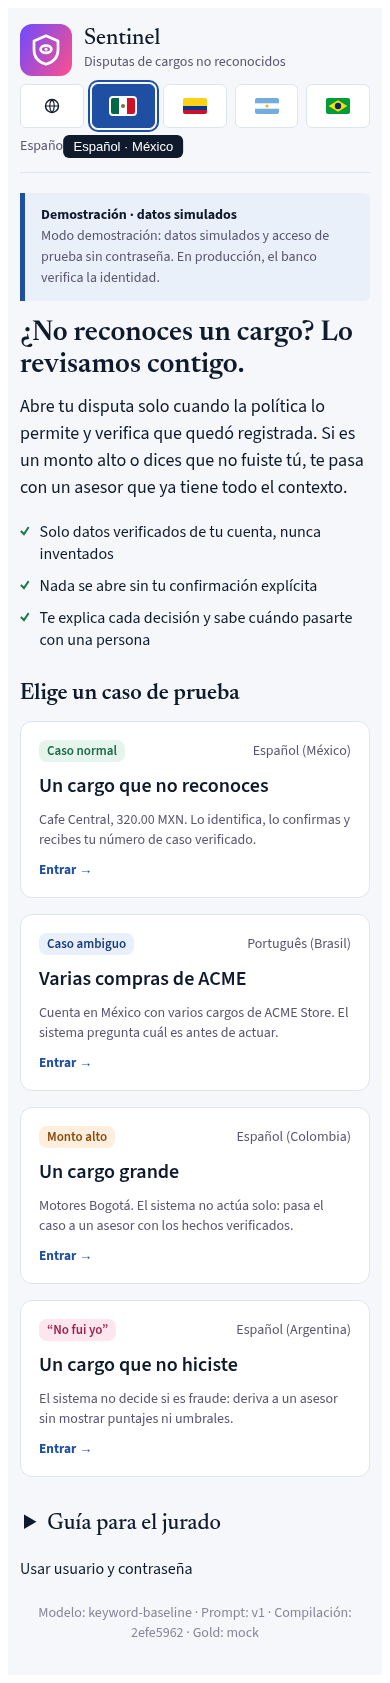
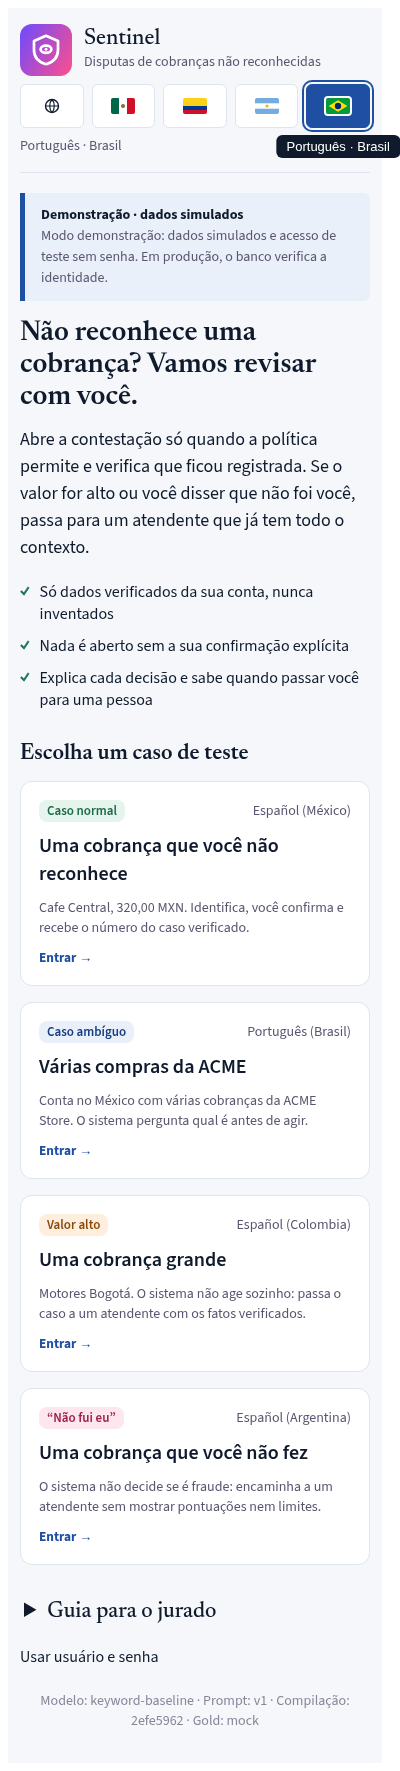
The customer replies in es-MX, es-CO, es-AR or pt-BR. The data is synthetic. The Gold store is a labelled mock.
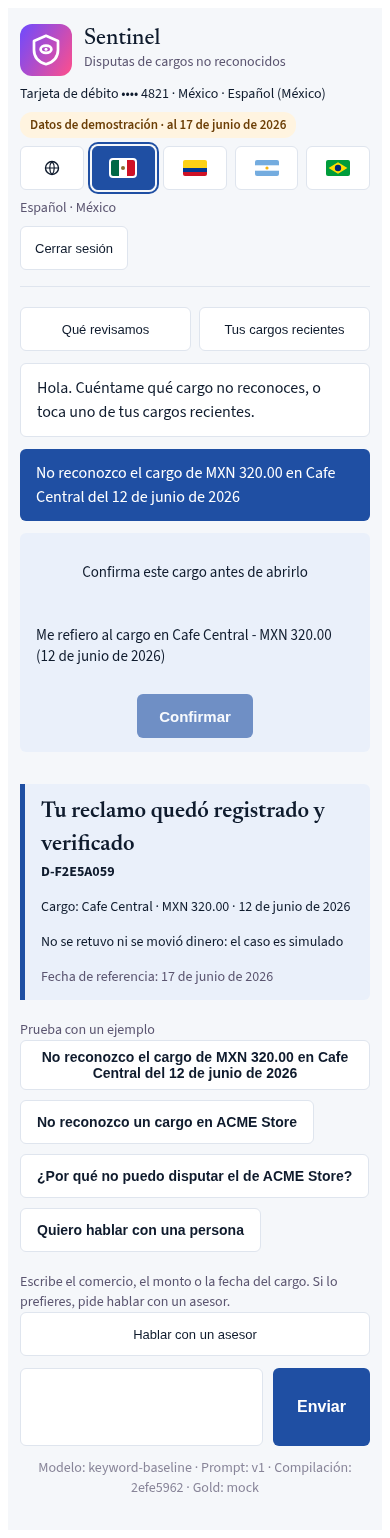
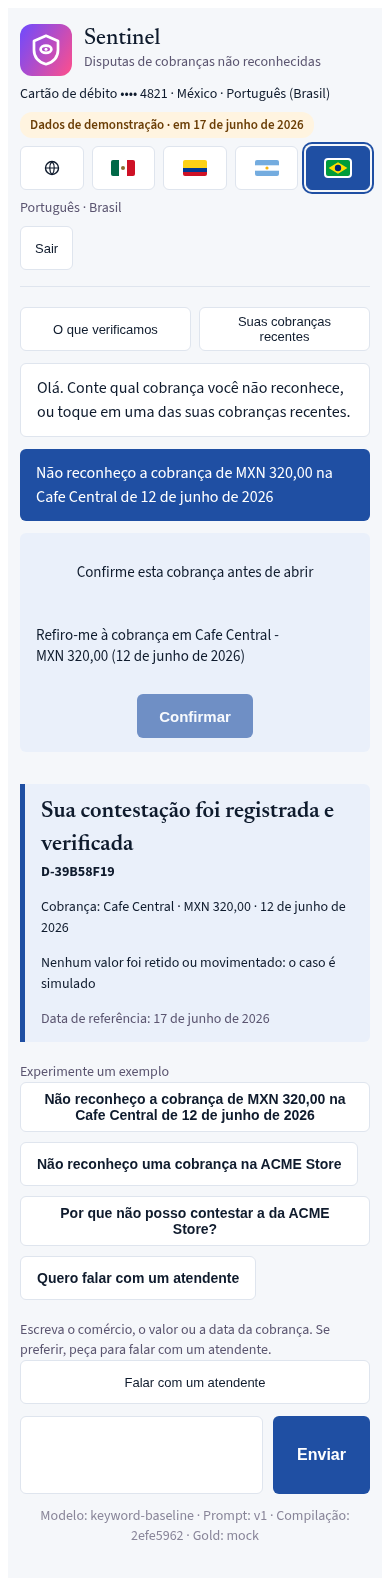
One charge, one confirmation, one verified case number.
Several equal purchases. The system asks which one before it acts.
The system does not act alone. It hands off with the verified facts.
The system does not decide on fraud. It hands off to an advisor.
Cases. The live demo is retired. The four cases and the demo lines stay in the demo replay.
Screenshots
Real screens of the running demo on a phone, in Spanish and Portuguese. The demo uses test data and the keyword baseline. Each screen footer says so. The screenshots come from scripts/capture_ui_product.py.
Limits and roadmap
Limits
- Data: synthetic, in Spanish only, for three countries. A model wrote the Portuguese cases.
- Ceiling: the policy lets 16 of 56 simulated cases resolve (Simulation). The system resolves all of them. It resolves no other.
- Mocks: the Gold store, login and session, the advisor, the case store and the policy values. Each keeps the production contract. Mocks.
- Translations: a model wrote the Spanish and Portuguese pages from the English pages. No native speaker reviewed them.
- Numbers: no number is a production measurement.
Roadmap: not built
- Customer 360: the balance has no usable as-of date.
- Charge investigation: it needs real bank data.
- Feedback dataset: the outcomes of advisor handoffs.
- Spending assistant: it needs balances and history.
- Policy retrieval: it needs the policy documents of the bank.
- Handoff routing: by language and specialty.
Each item has its evidence in the README roadmap.